
↑Part of: Unredacted NYT filings show Microsoft exec called AI scraping ‘largest theft of labor,’ detail paywall bypassing


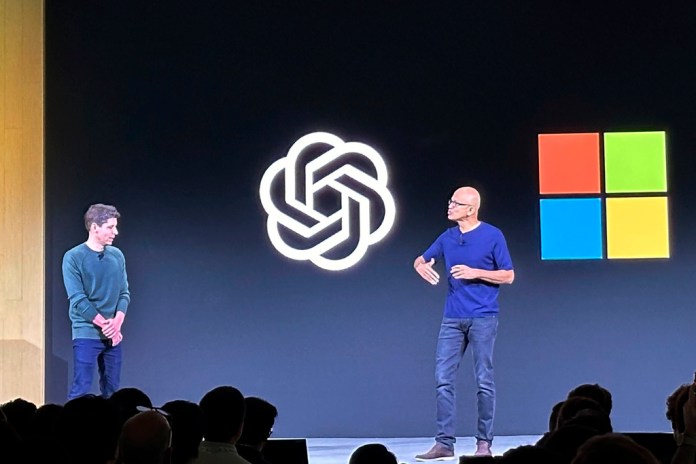
Microsoft and OpenAI warned their AI would 'hurt the web' and threaten news business, court filing shows
Topic: technologyRegion: north americaUpdated: i2 outletsSources: 5⚠ Bias gap — sources divergeSpectrum: Mostly Center⏱ 2 min read
Story Summary
SITUATION
OpenAI and Microsoft executives told a court their AI models ingest news articles and could create a ‘doom loop’ that threatens the commercial foundations of news publications (per Washington Examiner). The revelation appears in a largely unredacted filing unsealed September 17, 2026 as part of The New York Times' copyright suit (per Washington Examiner).
Coveragetap to expand ▾Spectrum: Mostly Center🌍US: 1 · ME: 1
Political Spectrum
Position is inferred from coverage mix.
i2 outlets · Center
Left
Center
Right
Left: 0
Center: 1
Right: 1
Geography Coverage
Distribution of where coverage is coming from.
i2 unique outlets · Dominant: US/Canada
KEY FACTS
- Executives warned the models could create a 'doom loop' threatening the economic foundations of news publications (per Washington Examiner)
- The court filing was unsealed September 17, 2026 as part of The New York Times' copyright suit against OpenAI and Microsoft (per Washington Examiner)
HISTORICAL CONTEXT
The immediate backdrop is the ongoing U.S.–Israeli military campaign that began with coordinated strikes on Iran in March 2026 and has since produced a series of Iranian military responses across the region. Structurally, the dispute sits atop long-standing legal frameworks governing intellectual property and the internet — notably the U.S.
Copyright Act (1976) and the Digital Millennium Copyright Act (1998) — and, for Europe, the 2019 EU Copyright Directive (Article 15) that empowered publishers to seek licensing and remuneration from platforms.
Brief
Top executives at OpenAI and Microsoft told a court that their AI models ingest news articles and warned those systems could create a 'doom loop' that undermines the commercial foundations of news publishers, according to a largely unredacted filing unsealed September 17, 2026.
The disclosure surfaced in The New York Times' copyright lawsuit and lays out in the companies' own words how their models rely on scraped reporting and could reduce incentives for journalism to be produced and paid for.
The filing, as reported by the Washington Examiner, records internal acknowledgments that generative models consume news content and that widespread use of model outputs may shift user attention and ad spending away from original reporting.
OpenAI and Microsoft have argued elsewhere that their systems transform and add value to training inputs; the court filing cited by the Examiner documents the companies' internal recognition of direct consumption of news text, a fact plaintiffs are using to press copyright claims.
The timing of the unsealing — linked to ongoing litigation by The New York Times — sharpens questions about whether existing copyright law and licensing markets can adapt to large-scale AI training practices.
For news organizations, the filing provides a contemporaneous admission from defendants that supports claims of economic harm; for the companies, it is part of a broader legal record in which they also assert defenses based on transformation and fair use.
Expect the court record to shape negotiations over licensing terms or statutory fixes that Congress or regulators might consider, even as the suit proceeds through the courts.
Why it matters
- News publishers bear concrete economic risk: the filing says AI models consume news articles and could create a 'doom loop' that undermines publishers' revenue model (per Washington Examiner), threatening journalists' jobs and news output.
- The New York Times and other subscribing news organizations stand to gain leverage in copyright litigation because defendants' own filing documents use of news content (per Washington Examiner).
- OpenAI and Microsoft could face licensing costs or damages if courts find their training practices infringe copyrights, which would alter their AI development and business models (per Washington Examiner).
What to watch next
- Whether the court handling The New York Times' copyright suit admits the unredacted filing as evidence in upcoming hearings and schedules a ruling or trial date.
- Whether The New York Times pursues discovery or depositions of OpenAI and Microsoft executives about the internal acknowledgment reported in the unredacted filing.
- Whether Congress or regulators introduce or accelerate legislation on AI training data or copyright licensing following the filing being unsealed on September 17, 2026.
Where sources differ
7 dimensionsBias gap0.50 / 2.0
Left- and right-leaning outlets are covering this story differently — in which facts to emphasize, which context to include, and how to frame causes and consequences.
Center (4)
trtworld.comstraitstimes.comfinance.biggo.comft.com
Right-leaning (1)
washington_examiner+0.70
Top executives at OpenAI and Microsoft acknowledged that their AI models consume news articles and could create a 'doom loop' that threatens the economic foundations of news public…
7 specific areas where coverage diverges — see below.
Framing differences
?- Only the Washington Examiner is in this pack; it frames the unsealed filing as an admission that supports The New York Times' copyright suit.
Disputed or unclear
?- No source in this pack disputes the core facts; broader disputes (e.g., about fair use or transformation) are referenced but not adjudicated in the provided text.
Omitted context
?- No source here provides details on the specific training datasets or proportion of news content used;
- No source mentions quantified financial losses to specific publishers tied to model use;
- No source cites any licensing offers or agreements between OpenAI/Microsoft and news organizations;
- No source references regulatory or statutory frameworks that might govern AI training reproducibly.
Conflicting figures
?- No divergent figures appear in the single provided source.
Disputed causality
?- The filing states company models consume news and warns of a 'doom loop'; the filing does not in this excerpt document a clear legal or market consequence timeline beyond the asserted threat.
Attribution disputes
?- Washington Examiner attributes the description of the filing and the 'doom loop' language to the unredacted court filing connected to The New York Times' suit.
Sources
5 of 5 linked articles
NYT says OpenAI, Microsoft committed 'theft of unprecedented proportions' using articles to train AI
trtworld.comSep 18Left
↗
OpenAI and Microsoft leaders knew AI may cause ‘doom loop’ hurting entire web
washingtonexaminer.comSep 18Center
↗
OpenAI, Microsoft executives’ quotes on AI training threaten copyright defence, news outlets argue
straitstimes.comSep 17Left
↗
Microsoft and OpenAI Executives Admitted AI Poses 'Existential Threat' to News, Unsealed Filings Show - finance.biggo.com
finance.biggo.comSep 17Left
↗
OpenAI staff knew the ‘existential threat’ AI posed to publishers, New York Times claims
ft.comSep 17Left
↗